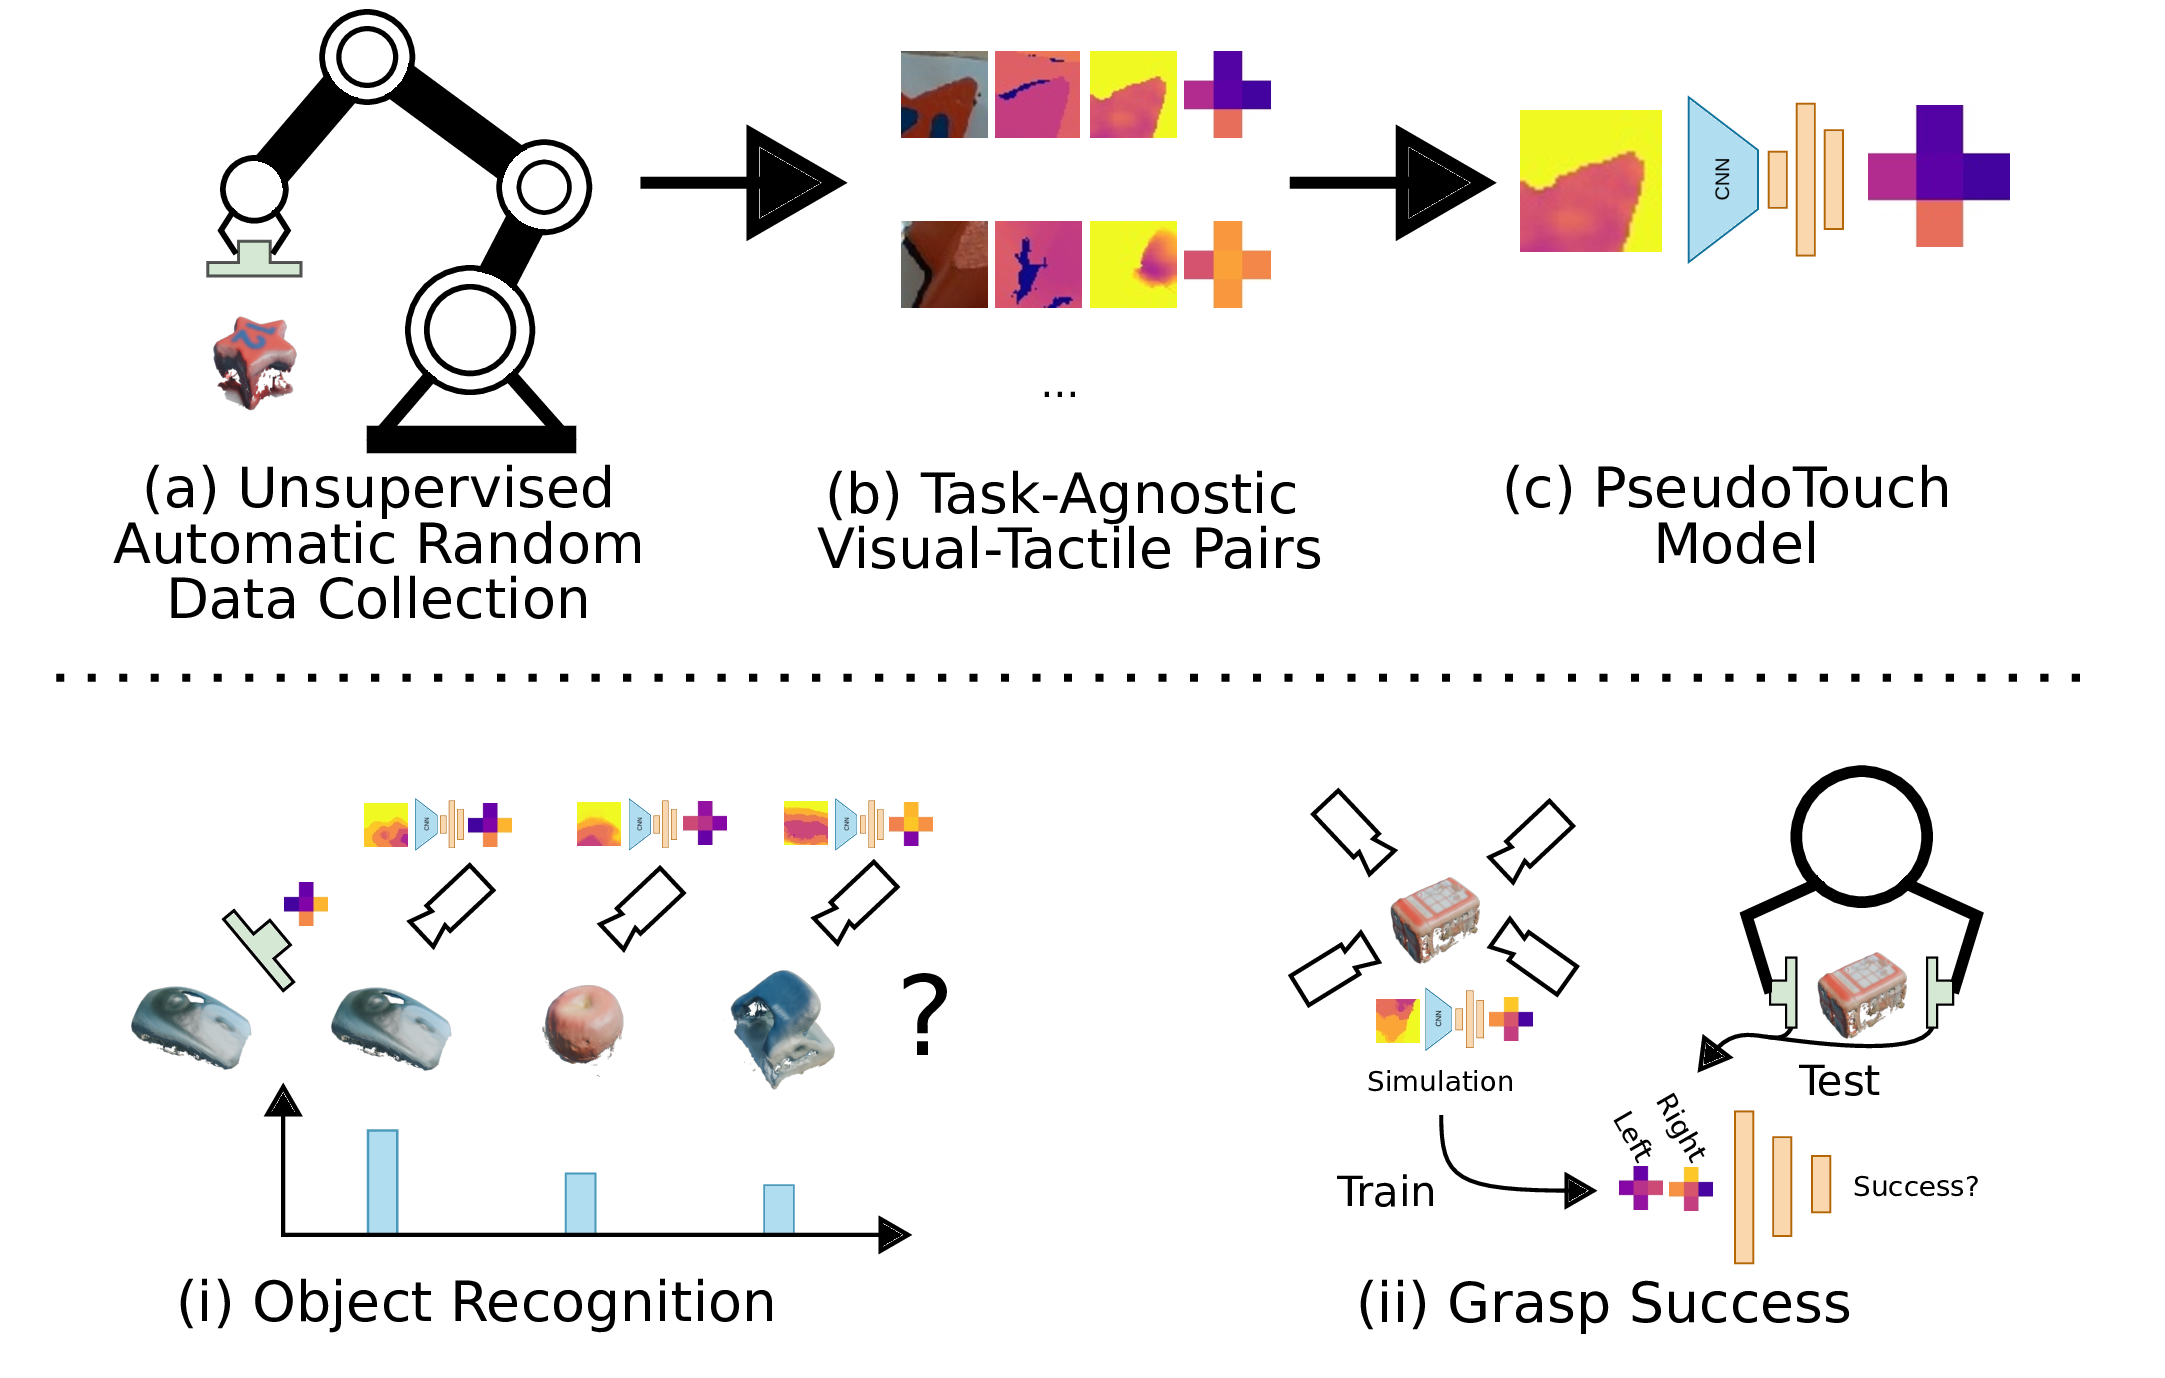Compact magnetic tactile sensors such as ReSkin are cheap and
easy to integrate, but they produce only a low-dimensional signal and, unlike optical tactile sensors, cannot be
simulated with standard rendering techniques. PseudoTouch addresses both issues by learning to predict the tactile
reading a sensor would produce from a small depth image of the touched surface. Once trained, the model acts as a
"virtual" touch sensor that can be queried on real or simulated depth data for different downstream tasks.
PseudoTouch Model
PseudoTouch is a function \(PT: z_d \mapsto \tilde{\tau}\) that takes a depth patch
\(z_d \in \mathbb{R}^{17 \times 17}\) of the object surface and predicts the tactile reading
\(\tilde{\tau} \in \mathbb{R}^{15}\) that touching this surface would produce. We implement it as a
light-weight convolutional encoder, followed by average pooling and a single-layer MLP. We deliberately keep the
model capacity low to avoid overfitting on our small dataset, given the large imbalance between input and output size.
Data Collection
We collect aligned visual-tactile pairs with a Franka Emika robot that carries a wrist-mounted RealSense D405 camera
and a 3D-printed finger holding a ReSkin sensor. The procedure is largely automated:
- Scan the fixed object with the wrist camera and reconstruct a surface mesh.
- Sample candidate touch points and normals from the mesh, rejecting overly flat approach angles and obstructed approach corridors.
- Solve for a camera pose observing the point along its normal, and for a pre-touch pose of the sensor.
- Record a depth image of the target area from the camera pose.
- Record an ambient sensor reading, then approach the surface along the normal until the reading deviates; the dataset item is the difference to the ambient reading.
- Project the sensor's contact area into the depth image to extract a 17 mm × 17 mm depth patch.
In total, we collect 1600 samples from eight primitive objects of a shape-sorting toy, which cover edges of
different curvature and points of different sharpness. Because our downstream tasks rely on simulated depth, we
close the gap between real and simulated observations by pairing each tactile reading with both the real depth
patch and a depth patch rendered from the object mesh at the same pose. Both are normalized to a 3 mm depth
range, excluding depth information the sensor cannot realistically capture.
Downstream Task 1: Online Object Recognition
Given a set of candidate objects \(O\) with known 3D models, the robot identifies the object it is touching by
performing a sequence of touches and updating its belief with a directed graphical model. For each candidate
object \(o\), PseudoTouch predicts the expected reading \(\tilde{\tau}_o\) at the measured contact location
\(l\) from a simulated depth patch, which yields the touch likelihood
\(p(\tau \mid o, l) = \exp(-\lVert \tilde{\tau}_o - \tau \rVert)\). A proprioceptive likelihood
\(p(l \mid o)\) scores how well the contact location fits the object's surface. Starting from a uniform prior,
the posterior after \(N\) touches is
\(\displaystyle p(o \mid x_1, \ldots, x_N) \propto p(o) \prod_{n} p(\tau_n \mid l_n, o)\, p(l_n \mid o)\).
New touches are planned by sampling an object hypothesis from the current posterior and sampling a touch location on it.
Downstream Task 2: Grasp Stability Prediction
We train a small MLP that predicts grasp success from the tactile readings of the left and right fingers. Instead of
collecting real grasps with tactile sensors, we generate the training data entirely in simulation: for annotated grasps
from the ACRONYM dataset, we render
depth patches with virtual orthographic cameras at the fingertips and use PseudoTouch to infer the corresponding
tactile signals. This turns an existing grasp dataset into a large-scale tactile grasp dataset without simulating a
tactile sensor or executing real grasps.